

Cultural Moment Benchmark: Evaluating Video Cultural Reasoning and Grounding in Southeast Asia
Paper • 2608.23065 • Published • 1
concept string | country string | status string | options list | category string | index string | momentname string | question_text string | question_moment string |
|---|---|---|---|---|---|---|---|---|
Nyepi | Indonesia | ok | [
"Waisak",
"Thimithi",
"Songkran"
] | celebration | 82 | m_Indonesia-celebration-Nyepi-016.mp4 | Which option represents the cultural concept that transitions from communal chaos to unified tranquility for universal equilibrium? | Which moment represents the cultural concept that transitions from communal chaos to unified tranquility for universal equilibrium? |
Paper | Project Page | Leaderboard | Walkthrough | SCB, the image predecessor
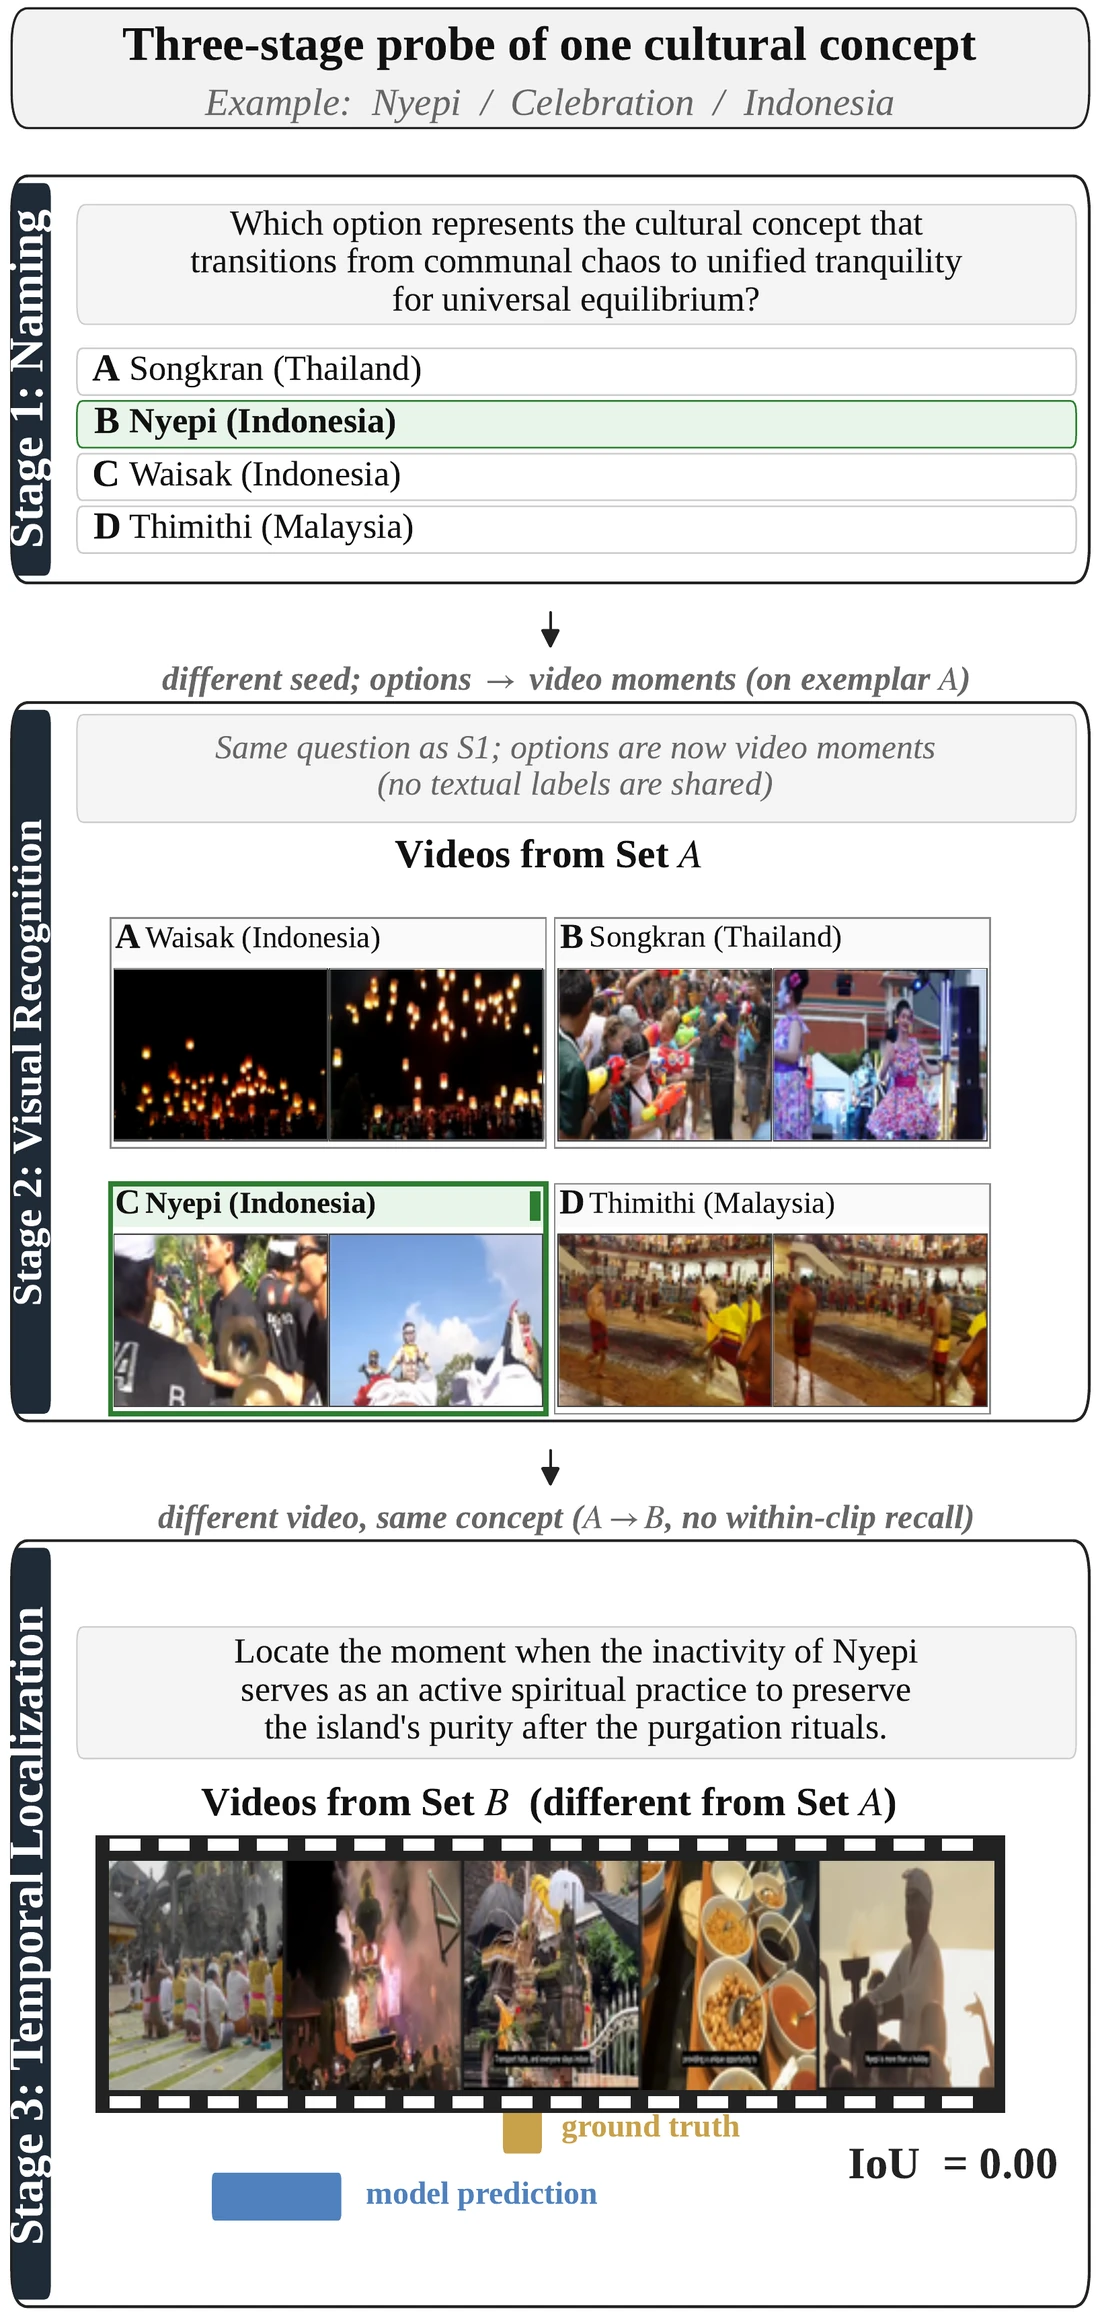
CMB evaluates how vision-language models reason about cultural moments in video across Southeast Asia. Each concept is tested in three stages: naming the concept, recognizing it visually in video, and temporally localizing its sub-events, under three context modes (Reset, Carry, Feedback).
The benchmark covers 306 expert-curated concepts from seven countries in Southeast Asia across five categories, drawn from 624 source videos, with 631 temporal localization pairs.
Available now: one sample concept, end to end. It is the walkthrough concept from the project page: Nyepi (Indonesia, Celebration). CMB is released in stages: a stratified public sample covering all seven countries and five categories, with the remaining items held back as a hidden test set for a planned shared task (a workshop at ACL 2027) and released once it concludes.
The benchmark ships annotations only. Source videos are not redistributed; the mapping of benchmark filenames to YouTube sources will be included in the full release.
data/sample/celebration_mcq.json: the Stage 1 and Stage 2 MCQ entry for the sample concept, in the same per-category format as the full release (keyed by concept name).data/sample/mcq_list.jsonl: the same MCQ entries flattened to one record per concept, for the dataset viewer.data/sample/vmr_videos.jsonl: Stage 3 temporal localization rows, one question per video, as on the project page (video filename, sub-event question, start and end times).data/sample/cultural_concepts.jsonl: naming variants for each concept (common/official, Latin/local script).Note: this sample is for exploring the data format. Results on the sample are not comparable to results on the full benchmark.
MCQ entries (celebration_mcq.json, keyed by concept name; mcq_list.jsonl, one record per concept with the key as concept):
country, category: the concept's country and one of the five categories.question_text: the Stage 1 question; question_moment: the same description phrased for Stage 2.options: the three distractor concept names. The correct answer is the concept itself (the JSON key, or concept in the jsonl), so a four-way question is the concept plus these three, shuffled.momentname: the Stage 2 moment clip of the concept (Set A); index: the concept's index in the full benchmark.status: ok for a validated item.Stage 3 rows (vmr_videos.jsonl, one question per Set B video):
Filename: the source video (Set B); Status: ACC for an accepted item.Question: the sub-event description to localize; Source: Curated for a Cultural-Annotator-written question.Time_start, Time_end: the human-annotated span, mm:ss; Duration: video length in seconds.Naming variants (cultural_concepts.jsonl): Common_Latin, Official_Latin, Common_Local, Official_Local, each with the country in parentheses.
from datasets import load_dataset

mcq = load_dataset("Multimedia-SMU/culturalmoment-benchmark", "sample_mcq")
vmr = load_dataset("Multimedia-SMU/culturalmoment-benchmark", "sample_vmr")
concepts = load_dataset("Multimedia-SMU/culturalmoment-benchmark", "sample_concepts")

print(mcq["sample"][0]["question_text"])      # Stage 1 question
print(mcq["sample"][0]["options"])            # the three distractors; the answer is the "concept" field
row = vmr["sample"][0]                        # Stage 3 row
print(row["Question"], row["Time_start"], row["Time_end"])
CMB is a test-only benchmark: please do not use it for training. The annotations and the evaluation suite are released under CC BY-NC-SA 4.0 for non-commercial research. Source videos are referenced by YouTube ID and are not redistributed; copyright remains with the original uploaders. The release contains no personally identifiable information: the metadata covers cultural concepts, timestamps and annotation records only.
If you uploaded one of the source videos and want it removed from the mapping, email buraks@smu.edu.sg; we will act on it promptly.
@misc{satar2026cultural,
    title={Cultural Moment Benchmark: Evaluating Video Cultural Reasoning and Grounding in Southeast Asia},
    author={Burak Satar and Zhixin Ma and Yu-Tong Cheng and Huy Hoang Tran and Phuong Anh Nguyen and Chong-Wah Ngo},
    year={2026},
    eprint={2608.23065},
    archivePrefix={arXiv},
    url={https://arxiv.org/abs/2608.23065}
}